Most AI “decisions” in production are small, and we are solving them with tools built to write essays.
On October 2, 2026, Databricks released a fundamentally different tool on Unity Gateway: OpenJev (Qwen3.5 4B). It doesn’t generate lengthy text replies or fragile JSON schemas. It scores choices directly in a single forward pass.
01Small Decisions, Essay Tools
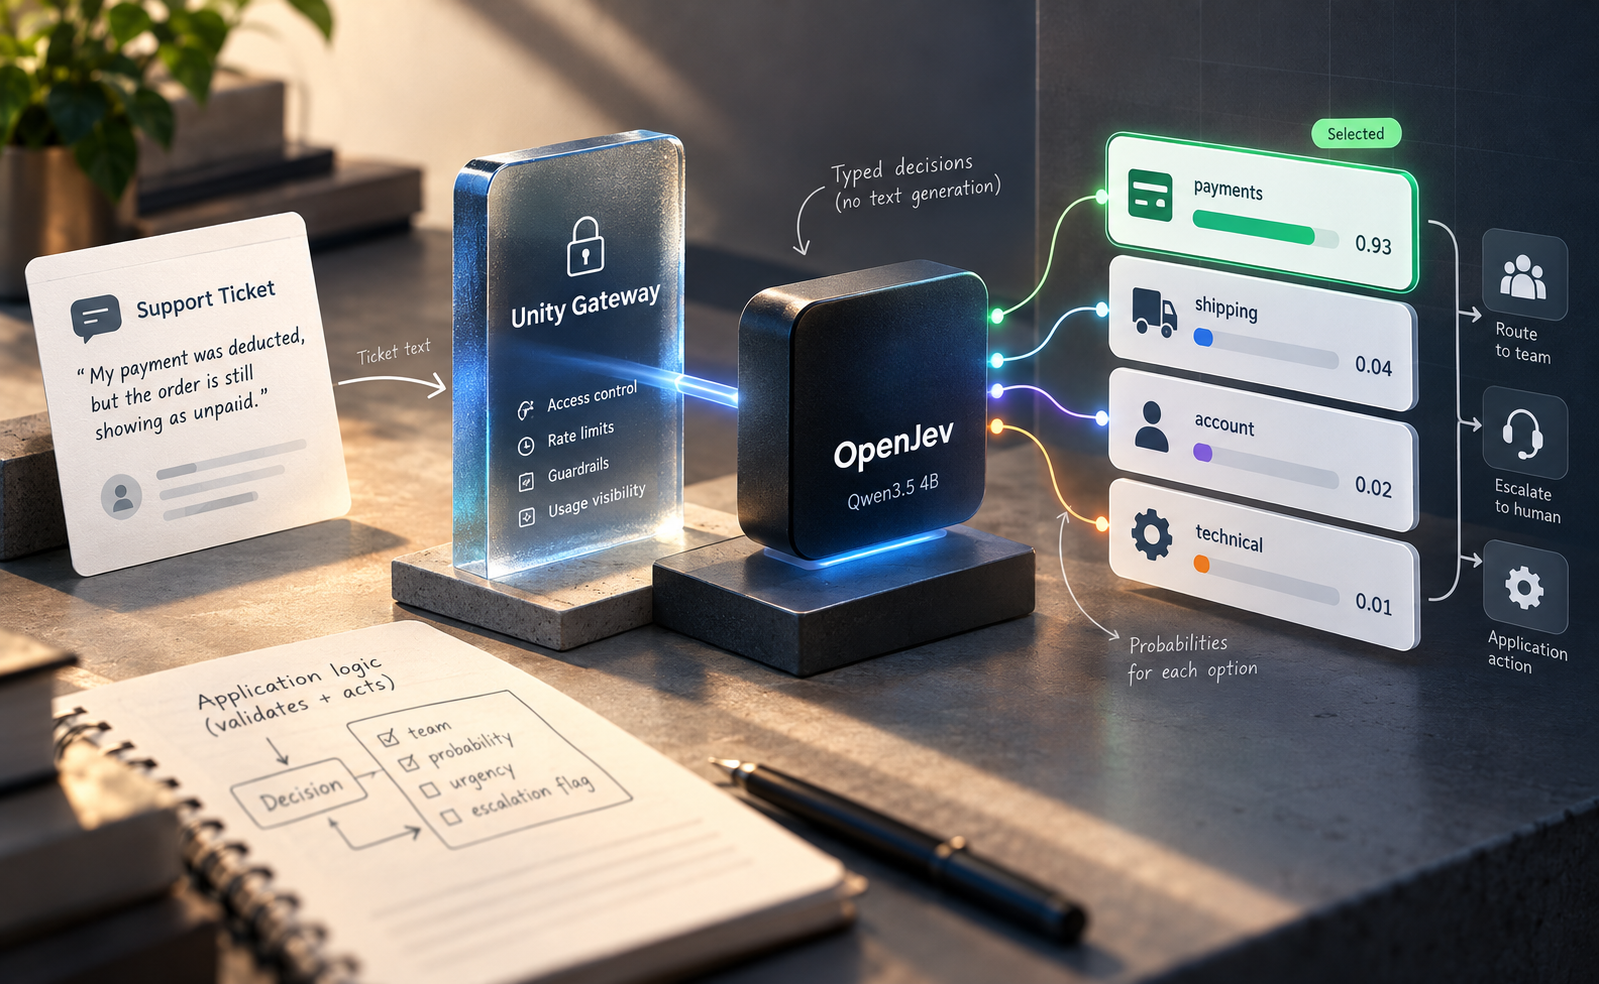
A customer writes: “My payment was deducted, but the order is still showing as unpaid.”
Your system needs exactly one thing: which team gets this ticket?
Today, standard practice prompts a 70B parameter large language model, asks for structured JSON, parses the reply, and hopes the format holds. When the format breaks or hallucinates keys, you add retry loops, JSON schema validators, and output parsers.
That is an enormous amount of machinery for a simple multiple-choice question. Every generated token adds latency and dollar cost, and every free-text answer introduces parsing and hallucination risk.
On October 2, 2026, Databricks made a different approach available on Unity Gateway with OpenJev (Qwen3.5 4B). It doesn’t write answers. It scores them.
02One Idea: The Model Decides, The App Acts, The Gateway Governs
The architecture relies on a clean, decoupled split of responsibilities across three distinct tiers. Most of its production value comes from keeping these three layers rigorously apart.
| Layer | Owns | Never does |
|---|---|---|
| Application | Business rules, state, authorization, and the final action | Hand authorization or autonomous write execution to the model |
| Unity Gateway | Access control, rate limits, enterprise guardrails, usage visibility | Replace application-level security and deterministic validation |
| OpenJev | One bounded judgment: pick an option, score it, or answer yes/no | Take the business action itself, trigger side-effects, or bypass gates |
The model’s output is an input to application logic. It never replaces it.
03How It Works: Read the Answer, Don’t Write It
OpenJev skips text generation entirely. You hand it a piece of text (the state), a question, and a closed set of options, and it returns a probability for each option in a single forward pass.
The Databricks release note describes the service as evaluating “yes or no, choice, and scoring questions” and returning structured answers with probabilities.
Structured-output modes in modern LLMs have made malformed JSON less common, so avoiding broken brackets is no longer the main argument. The core architectural difference lies in performance, determinism, and confidence calibration:
| Dimension | Generate a structured answer (LLM) | Read the probabilities (OpenJev) |
|---|---|---|
| Cost and latency | Pays compute and billing cost for every single generated token | One forward pass; zero generative output tokens generated |
| Confidence | A self-reported score the model fabricates about itself | A real probability distribution per option, read directly |
| Repeatability | Can vary run-to-run depending on temperature and token sampling | Bit-identical across repeated runs and shuffled option order |
| New decision type | Requires prompt rewriting, JSON schema testing, and error handling | Change the question enum string; no retraining or schema rework |
*Note: That is HysenLabs’ benchmark on their test hardware, not a Databricks platform guarantee. Always benchmark on your own workloads and data distributions.*
04Where It Comes From
Jev is an original proprietary decision service from TypeSafe, created specifically for the high-frequency micro-judgments that agentic software makes continuously - such as routing a ticket or deciding whether to retry an API call.
OpenJev recreates that interface using open model weights and does not reproduce TypeSafe’s internal model or proprietary training pipeline.
More than one implementation exists across the open-source ecosystem, so “OpenJev” is not a single codebase:
Score Reading from Existing LLMs
Extracts token probabilities directly from the logits of an existing foundation model without modifying the baseline weights.
Retrained Model for Judgment
Trains or fine-tunes a compact model specifically for decision scoring, invariant option ranking, and probability calibration.
The Databricks release notes explicitly cite Qwen3.5 4B and the “TypeSafe System One API”, offering a fully managed hosted gateway service for this paradigm.
05Why a Gateway Matters for Small Decisions
A model endpoint solves raw computational access to a model. A gateway solves the much harder problem: letting hundreds of engineering teams and autonomous agents consume it consistently.
On Databricks, Unity Gateway serves as the governed boundary. Applications invoke one managed path rather than wiring up ad-hoc model endpoints across services:
Ties model invocations to Unity Catalog service principals, catalog permissions, and granular workspace access tokens.
Offered as a pay-per-token managed service, allowing spend to be capped, monitored, and charged back to business units.
Enforces organization-level content filters and safety policies at the gateway boundary before payloads reach models.
A handful of option probabilities forms a compact, structured record that is easy to log, query, and audit in Delta tables.
*Note: Exact controls and availability depend on your Databricks workspace, region, and security tiers. Verify specific gateway features during architecture design.*
06Architecture and Request Flow
The gateway sits at the boundary, the model makes one bounded judgment, and the application retains the final word.
3 Lanes, 6 Steps: Application Boundary to Governed Gateway
Validate Request & Extract Minimal Context
The application authenticates the user and extracts only the text needed for the decision (e.g. ticket body). No customer PII or DB credentials are sent.
Call OpenJev Through Governed Gateway Path
The request crosses the gateway boundary. Unity Gateway enforces token limits, service-principal permissions, audit trails, and input safety guardrails.
Return Probability Distribution per Option
OpenJev evaluates the closed set of options in a single forward pass and returns raw probabilities for every allowed Choice and yes/no Noul question.
Reduce to Internal Typed Contract
The client reduces the gateway reply into a strict internal dictionary: team label, team probability, urgency score, and human escalation flag.
Apply Deterministic Business Rules
Deterministic Python code verifies if the score meets AUTO_ROUTE_MIN (e.g. 0.85). If confidence is low or order verification fails, human escalation triggers.
Perform Action or Route to Specialist
The ticket is routed into payments_queue with appropriate priority. The model never makes database modifications or refunds directly.
The exact endpoint, authentication headers, and request schema depend on your Databricks workspace configuration, so refer to Databricks documentation for endpoint URLs. Conceptually, a request carries the state text plus named questions: Choice (pick label), Score (scale), or Noul (yes/no probability).
07A Worked Example: The Payment Ticket
Let’s revisit our customer ticket: “My payment was deducted, but the order is still showing as unpaid.”
The application sends only the ticket text and the closed set of intents it supports. The model returns a probability for each option, and the application reduces that to a small internal contract:
| Field in the code | Example value | Where it comes from |
|---|---|---|
| team | "payments" | The selected label of the Choice answer |
| team_probability | 0.93 | The probability of that label returned by OpenJev |
| urgent | 0.12 | The Noul answer, a probability between 0 and 1 |
| Escalate to a human | No | Not from the model: Application threshold and safety checks |
The decision is not the end of the process. Deterministic application code still verifies that the user is authenticated, that the transaction ID exists, whether a refund is allowed, and whether a supervisor must review it. If confidence falls below your validated threshold, the ticket goes straight to a human.
08The Call: The SDK Wrapper
The community SDK for the System One API wraps the request. You pass the state (here the ticket text) and a dictionary of named questions. Each question is one of three types:
Pick a discrete label from a closed set with clear criteria.
Place the input state onto an ordered numeric scale.
A calibrated yes/no binary probability between 0 and 1.
from typesafe_sdk import TypeSafeClient, Choice, Noul

# Point at your Databricks gateway endpoint and credentials
client = TypeSafeClient(...)

QUESTIONS = {
    "team": Choice(
        instructions="Which team should handle this support ticket?",
        criteria={
            "payments": "Charges, refunds, failed or duplicate payments",
            "shipping": "Delivery status, delays, lost parcels",
            "account": "Login, profile and access problems",
            "technical": "Bugs, errors, integration problems",
        },
    ),
    "urgent": Noul(instructions="The customer is blocked or losing money right now."),
}

def decide(ticket_text: str) -> dict:
    response = client.system_one(ticket_text, QUESTIONS)
    team = response.choices["team"]
    return {
        "team": team.choice,
        "team_probability": team.probabilities[team.choice],
        "urgent": response.nouls["urgent"].noul,
    }
The response is fully typed. A Choice answer carries the selected label plus a probability for every label, and a Noul answer carries one probability between 0 and 1. The reduction in decide() creates the minimal internal contract.
09The Rest of the Application Code
Everything after decide() is ordinary deterministic code. The model picks a queue, and your business rules decide what is permitted:
AUTO_ROUTE_MIN = 0.85   # placeholder: set from your evaluation
URGENT_MIN = 0.70       # placeholder: set from your evaluation

def handle_ticket(ticket):
    try:
        d = decide(ticket.text)
    except Exception:  # gateway down, timeout, quota or permission error
        return send_to_human(ticket, reason="model_unavailable")

    audit_log(ticket.id, d)  # keep the probabilities, not just the winner

    if d["team_probability"] < AUTO_ROUTE_MIN:
        return send_to_human(ticket, reason="low_confidence")

    priority = "high" if d["urgent"] >= URGENT_MIN else "normal"

    if d["team"] == "payments":
        # Business facts and permissions come from your systems, never the model
        order = orders.get(ticket.order_id)
        if not ticket.user.is_authenticated or order is None:
            return send_to_human(ticket, reason="cannot_verify")
        return payments_queue.add(ticket, order=order, priority=priority)

return QUEUES[d["team"]].add(ticket, priority=priority)The model doesn’t issue a refund, grant access, or touch a customer database. It chooses a queue and flags urgency. Every single failure mode (gateway outage, timeout, low confidence, unauthenticated caller) ends safely with a human agent.
Keeping the internal contract this small also eliminates tight coupling: your business logic depends on a handful of primitive fields, not on how any one model formats its output.
10Security: A Gateway Is a Boundary, Not a Shield
The model card for the Qwen3.5-based OpenJev checkpoint is candid on this point: it reaches only about 60% accuracy as a security reviewer and is “not hardened against prompt injection.”
You must design your enterprise systems with that reality in mind:
Never Let Model Output Alone Authorize a Sensitive Action
Refunds, access grants, credit updates, and anything irreversible stay behind deterministic application authorization checks.
Treat the Input as Untrusted
A support ticket body is attacker-controlled text. Always validate what comes back against your allowed enum options in code.
Send the Minimum Context
Don't put secrets, API keys, credentials, or sensitive application state into the payload just because the model can receive them.
Use Least Privilege
Grant the application only the Unity Gateway catalog permissions and API scopes that the workflow strictly needs.
Keep a Human Path
For high-impact workflows, define confidence thresholds (e.g. probability < 0.85) below which the model is not trusted to act automatically.
11Is It Good Enough? Measure, Don’t Assume
The right architectural question is never which model is biggest. It is the smallest model that meets the quality and reliability bar for your specific workload.
The model card reports 0.622 accuracy on the hard tier of its JevBench benchmark. Nuanced or adversarial cases will be misclassified.
Probabilities represent relative preferences among the options provided, not absolute real-world frequencies. Option wording and order can sway scores.
Before moving to production, evaluate OpenJev as a comprehensive system on your real business data:
12What to Take Away
A useful AI system in the enterprise is rarely just a model. It is a model combined with the controls, application logic, and operational discipline that make it safe and cost-effective in production.
- Use a decision model for decisions: Reading probabilities gives real scores to threshold, with zero text generation overhead.
- Put it behind a governed entry point: Unity Gateway makes access, spend, and usage visible from day one.
- Keep business rules in deterministic code: Never delegate irreversible writes or financial operations directly to models.
- Treat the model as unproven: Evaluate on your data, calibrate thresholds, and measure cost per business outcome.
A Challenge for This Week
Pick one narrow routing or triage decision you currently hand to a large language model. Write down the allowed options, measure your current process as a baseline, and test a compact decision model against your hardest cases. Then tell us what you found.
13Sources & Citations
Checked and cross-referenced October 6, 2026:
- Databricks release notes, October 2026Unity Gateway OpenJev availability and API specifications
- OpenJev model card, Hugging FaceQwen3.5 4B checkpoint, JevBench benchmarks, safety findings
- OpenJev: open Jev baseline on a 4B model, HysenLabsLatency comparison: 1.02s vs 5.30s
- I read OpenJev and thought of an alternative solution using non-generative AI, ClassmethodCalibration and probability extraction analysis
- open-jev-on-databricks, GitHubCommunity implementation patterns for Databricks Model Serving
- A Coding Guide to TypeSafe AI Jev, MarkTechPostChoice, Score, and Noul primitive design
- typesafeai-systemone-jev-go, GitHubSystem One API specification
At Abilytics, we build governed AI systems where models provide bounded intelligence and enterprise platforms provide deterministic security, auditability, and scale. Moving from unbounded JSON generation to typed decision models is one of the highest ROI architectural optimizations an engineering team can make.
Evaluating decision models, Unity Gateway, or Databricks AI architectures?
Consult Our AI Architecture Team